12 posts tagged with "Platform Engineering"

Internal developer platforms and platform engineering

View All Tags

Run your own AI models, skip the machinery

· 12 min read
Rajesh RC
Founder

Every AI initiative starts with a choice: buy tokens from a frontier lab, or run models in your own cloud account.

For many teams, the lab API is the right answer. But renting is not an option when you need conditions a lab cannot sell you. You might need weights you own and can pin indefinitely, data that never leaves your infrastructure, predictable costs at scale, or independence from a model provider's roadmap.
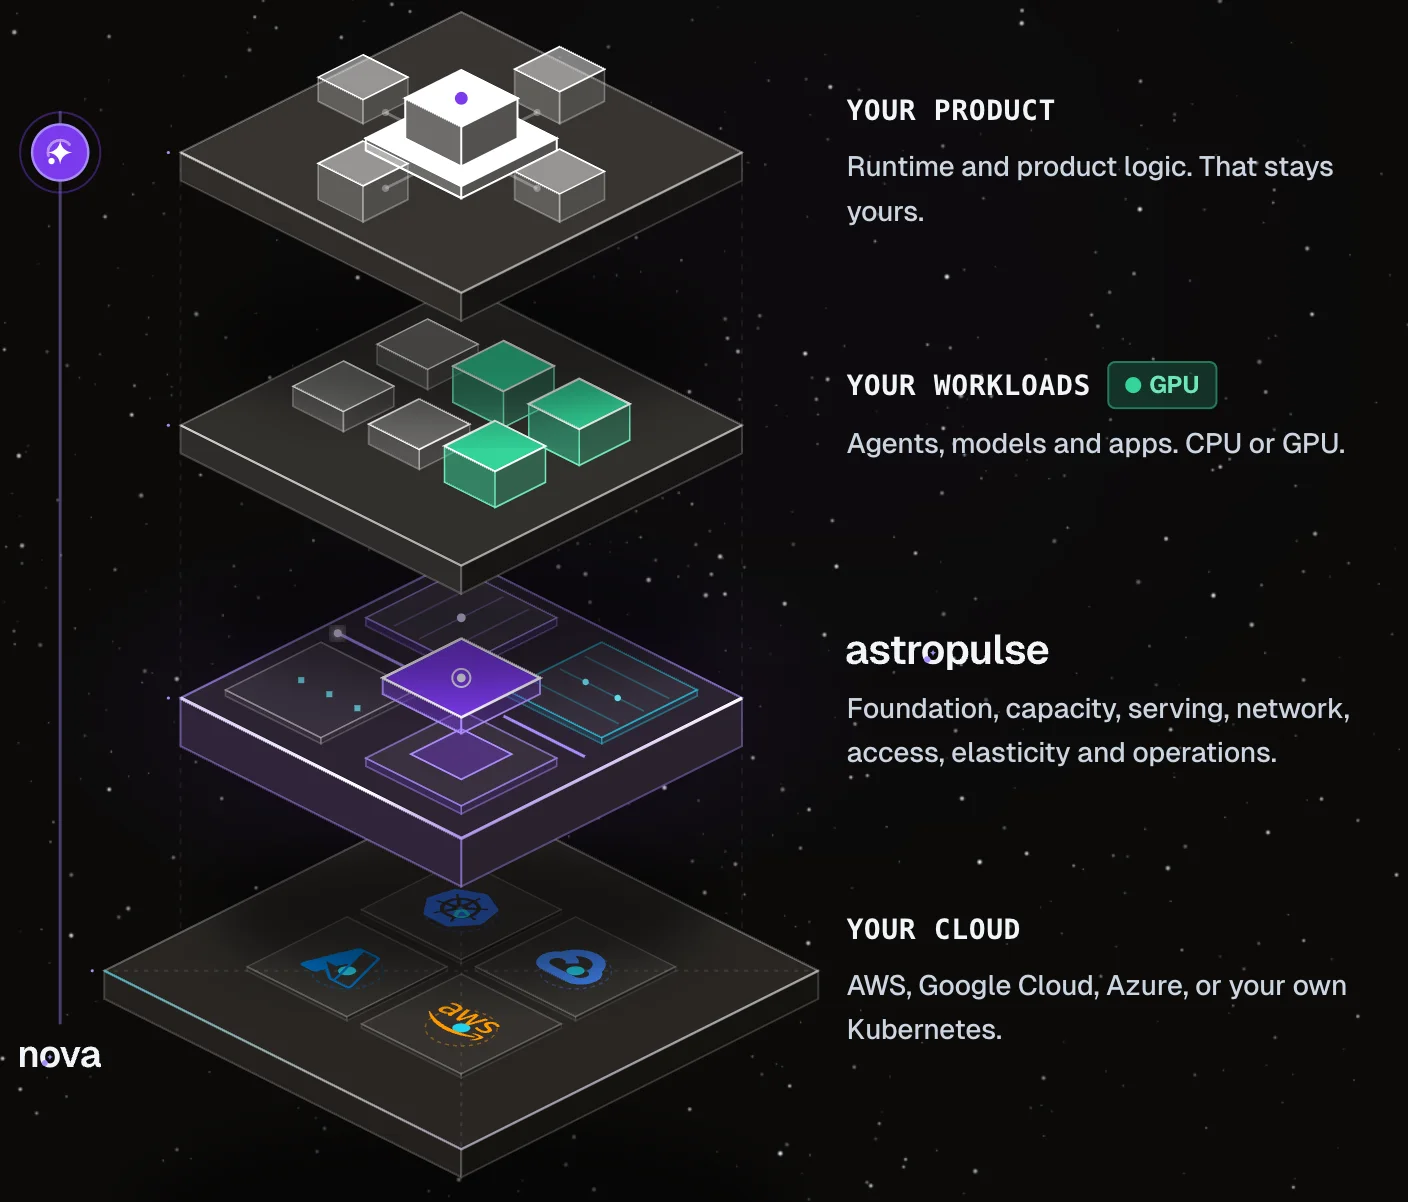
The AstroPulse stack: your product on top, your workloads (agents, models and apps on CPU or GPU) below it, AstroPulse in the middle running foundation, capacity, serving, network, access, elasticity and operations, and your cloud (AWS, Google Cloud, Azure or your own Kubernetes) at the base, with Nova alongside

How Nova picks the right tool out of thousands

· 10 min read
Rajesh RC
Founder
The thesis

At scale, search finds the tools. Judgment picks one.

With thousands of tools, getting the right one into a list of 100 is cheap. Getting it into the 5 the model sees, and knowing when none fits, is the hard part. A score that tracks the outcome is what lets the control layer act instead of guess.

Nova is our AI platform engineer. It does Day 1 work, building and shipping infrastructure, and Day 2 work, running it: scaling, upgrades and incidents, where it acts as an AI SRE. Either way it works through skills: its own, plus every MCP server an organization connects. Connect a few observability tools, source control, a cloud account and some internal servers, and the catalog is thousands of tools. On every turn Nova has to put the handful that fits in front of the model.

This post is the engineering behind that: the pipeline, what each step was worth on a public benchmark, what did not work, and how to reproduce it.

Kubernetes Standardized the Primitives. Nobody Standardized the Platform.

· 9 min read
Rajesh RC
Founder
The thesis

Kubernetes standardized infrastructure primitives. Nobody standardized the glue above them.

Every company needs a different platform blueprint. They should be able to compose it from shared capabilities and production controls, inside infrastructure they own.

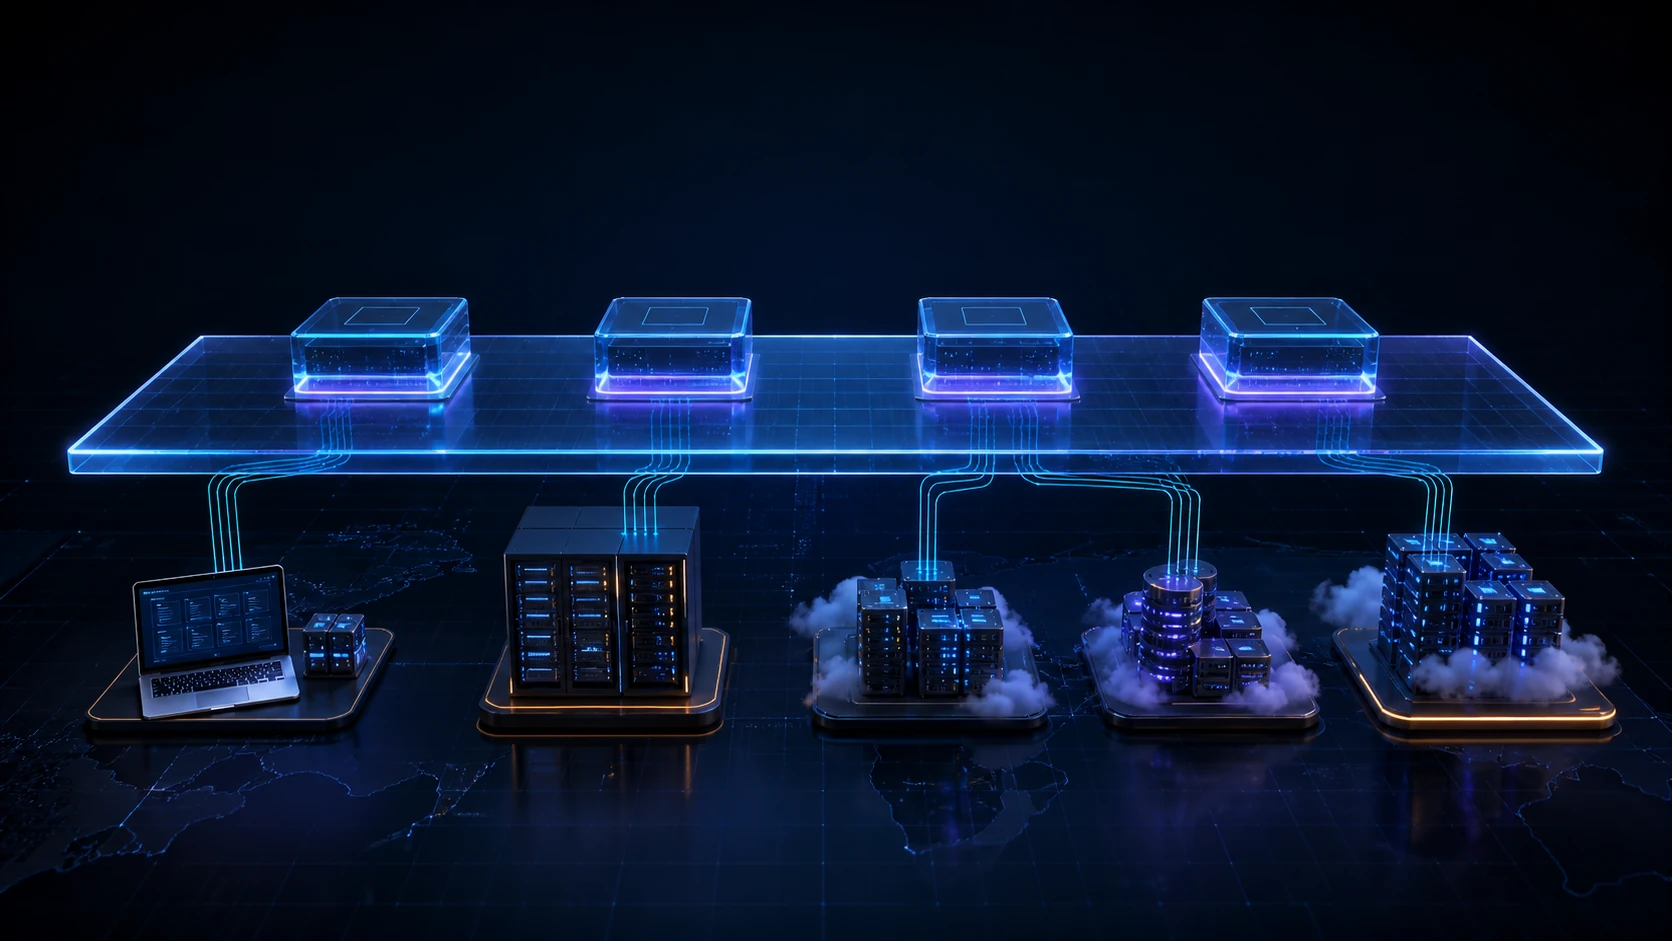
One continuous platform layer spanning a developer laptop, on-premises servers, and several cloud infrastructure environments

Different infrastructure underneath. One foundation for the blueprint you choose.

Here is a small thing that still delights me. Take the kind cluster running on your laptop, run one command, and it shows up in the same console as a production cluster on EKS: same deploy pipeline, same add-ons, same cost view. Not a simulation of production. The same blueprint running on the same foundation.

I want to explain why we built it that way, because behind that small trick sits our entire argument about how infrastructure should work for startups and mid-size companies. It starts with giving Kubernetes credit for what it actually standardized, and being honest about what it never did.

You Pay for Cluster Capacity, Not Average Usage

· 7 min read
Rajesh RC
Founder

Requests are not waste: teams use them to preserve schedulable capacity for bursts, startup spikes, and reliability. They also determine how workloads fit on nodes, so more headroom than a workload needs can block consolidation or occupy capacity another workload could use.

AstroPulse shows requests beside time-averaged usage for every cluster, namespace, and application. The gap starts an investigation; it does not prescribe a new request.

Four cluster capacity blocks with small illuminated cores representing the gap between reserved and used resources

Compare requested headroom with average use, then decide whether the gap is intentional.

Your Startup Needs a Deployment Platform, Not a Platform Team

· 8 min read
Rajesh RC
Founder

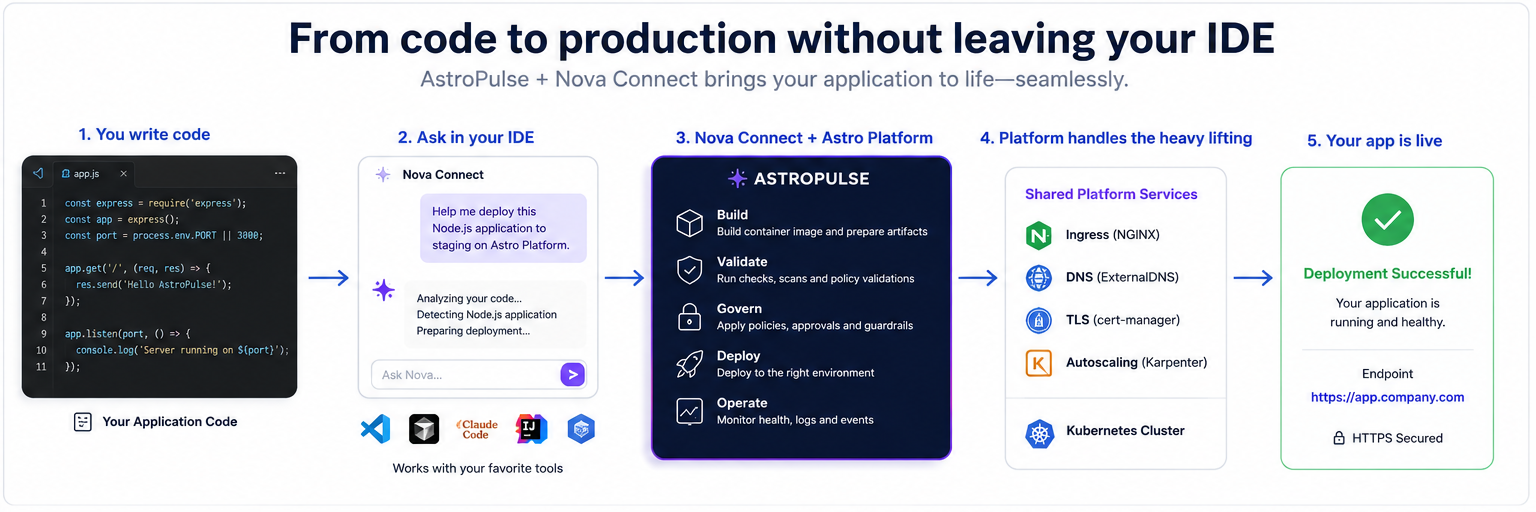
Many startups begin with one application and a hosted deployment service. That is usually the right decision. The team can ship without first building networking, deployment automation, or an operations layer.

The requirements change as the company adds services, environments, enterprise customers, private networking, and infrastructure ownership. The team still needs a short path to production, but the applications now need to run in infrastructure the company controls.

AstroPulse gives growing engineering teams a repeatable path from code to production in infrastructure they control, without requiring them to build the platform themselves.

From code in an editor through Astro Platform services to a healthy application, with one platform reused across multiple services

From code in the editor to a healthy application, with one platform reused across multiple services.

The AI SRE Race Is Running the Wrong Way

· 7 min read
Rajesh RC
Founder
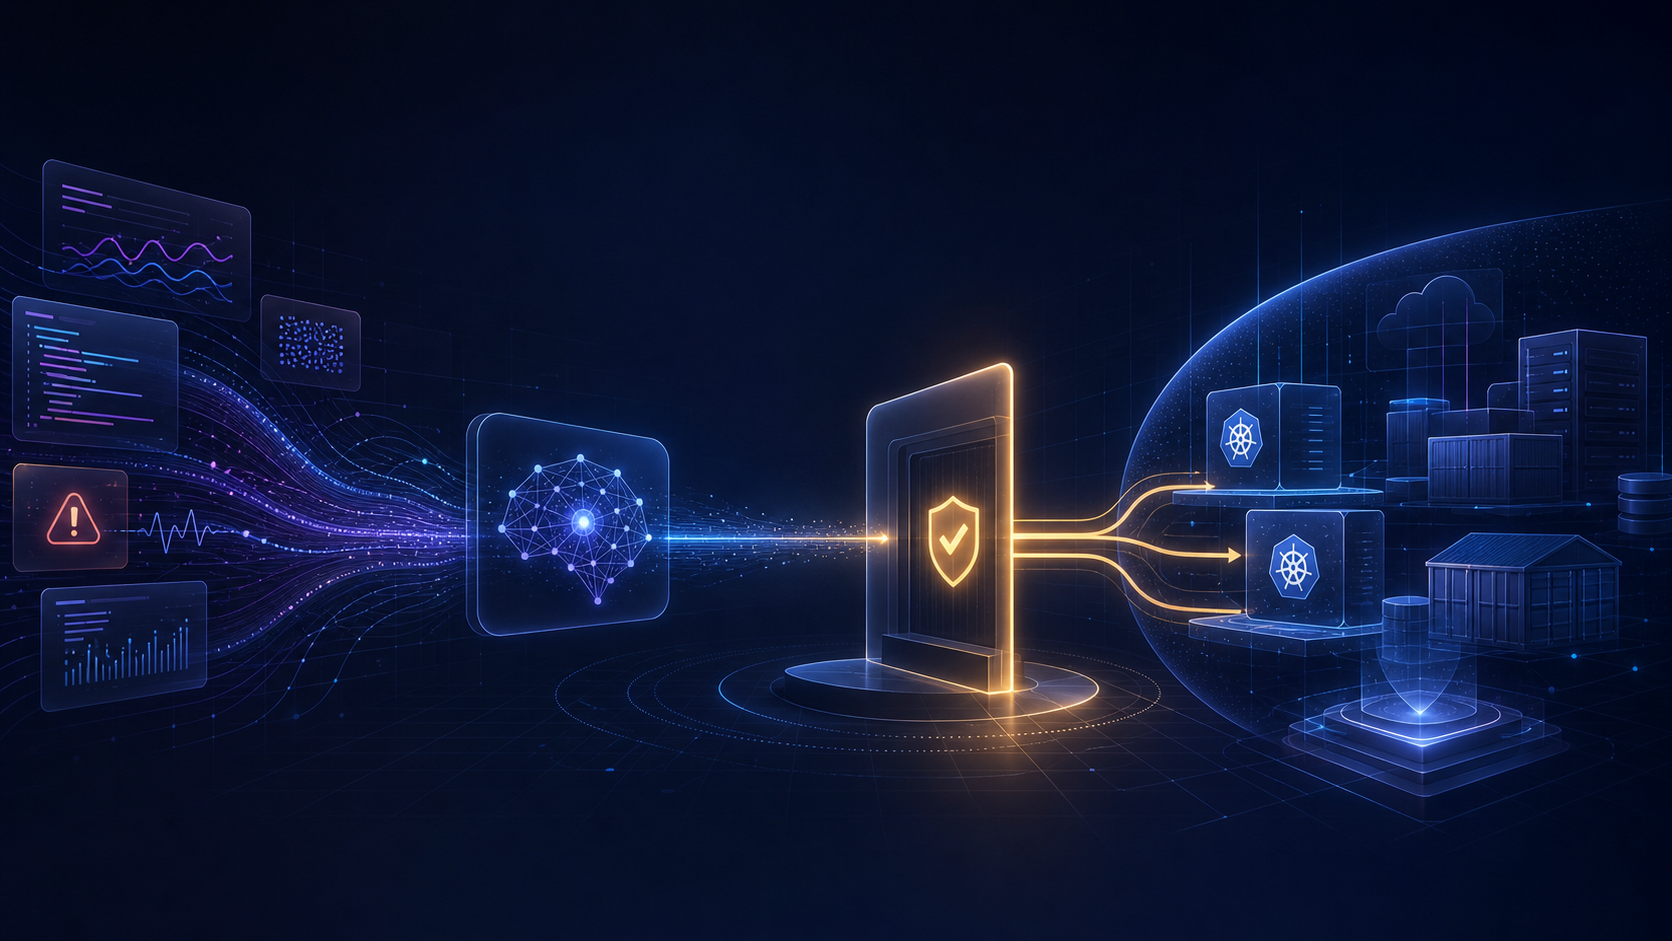
AI diagnosis flowing through a governed approval gate into production infrastructure
The thesis

Diagnosis is a commodity. Trust is the product.

The AI SRE race will not be won by the agent that diagnoses fastest. It will be won by the system that operators trust enough to grant write access.

A personal note on where AI for operations is actually heading.

Over the past year a new category filled up fast. Depending on how you count, there are now more than a dozen credible tools that call themselves AI SREs. I have watched the space closely, partly because we are building in it, and partly because the speed of convergence is genuinely interesting.

Here is what nearly all of them do. They connect to your telemetry, your code, and your incident tooling. They correlate logs, metrics, and traces. When an alert fires, they form hypotheses, test them against the evidence, and post a likely root cause into Slack, often in under a minute. This is real progress. A few years ago none of it worked. Today most of it does.

Phase one is real

Diagnosis is real progress. But it is just phase one.

How We Designed Nova's Investigation Engine: Lessons from SRE at Scale

· 8 min read
Rajesh RC
Founder

When something breaks in production at an odd hour, the person on call has to do three things at once: understand what is happening, decide what to do about it, and be able to explain all of it the next day. Most AI incident tools help with at most one of these. They either give you more data to read, or they take action you cannot see and cannot account for afterward.

We spent the last several months building Nova's investigation engine around that gap. This post is about how we designed it, the models we borrowed from, and the trade-offs we made along the way.

Bring Your Own Kubernetes Cluster

· 5 min read
Rajesh RC
Founder

Six months in as platform lead and you have a spreadsheet you haven't shown your manager. Eleven Kubernetes clusters. EKS for production. GKE for the ML team. Two on-prem clusters behind the firewall that predate your tenure. A handful of Kind clusters developers spun up locally. Each one has its own deployment pipeline, its own credentials rotation process, its own way of answering "is this service healthy?"

Your team isn't building features anymore. You're maintaining eleven slightly different versions of the same tooling.

Terminal
astroctl infra k8s register --name my-cluster